As generative AI moves from pilots into production, governance increasingly depends on the infrastructure carrying data, enforcing access controls and supporting systems across cloud, on-premises and edge environments. Singapore’s guidance on GenAI transparency and privacy-enhancing technologies adds another set of expectations for enterprises operating across the region.
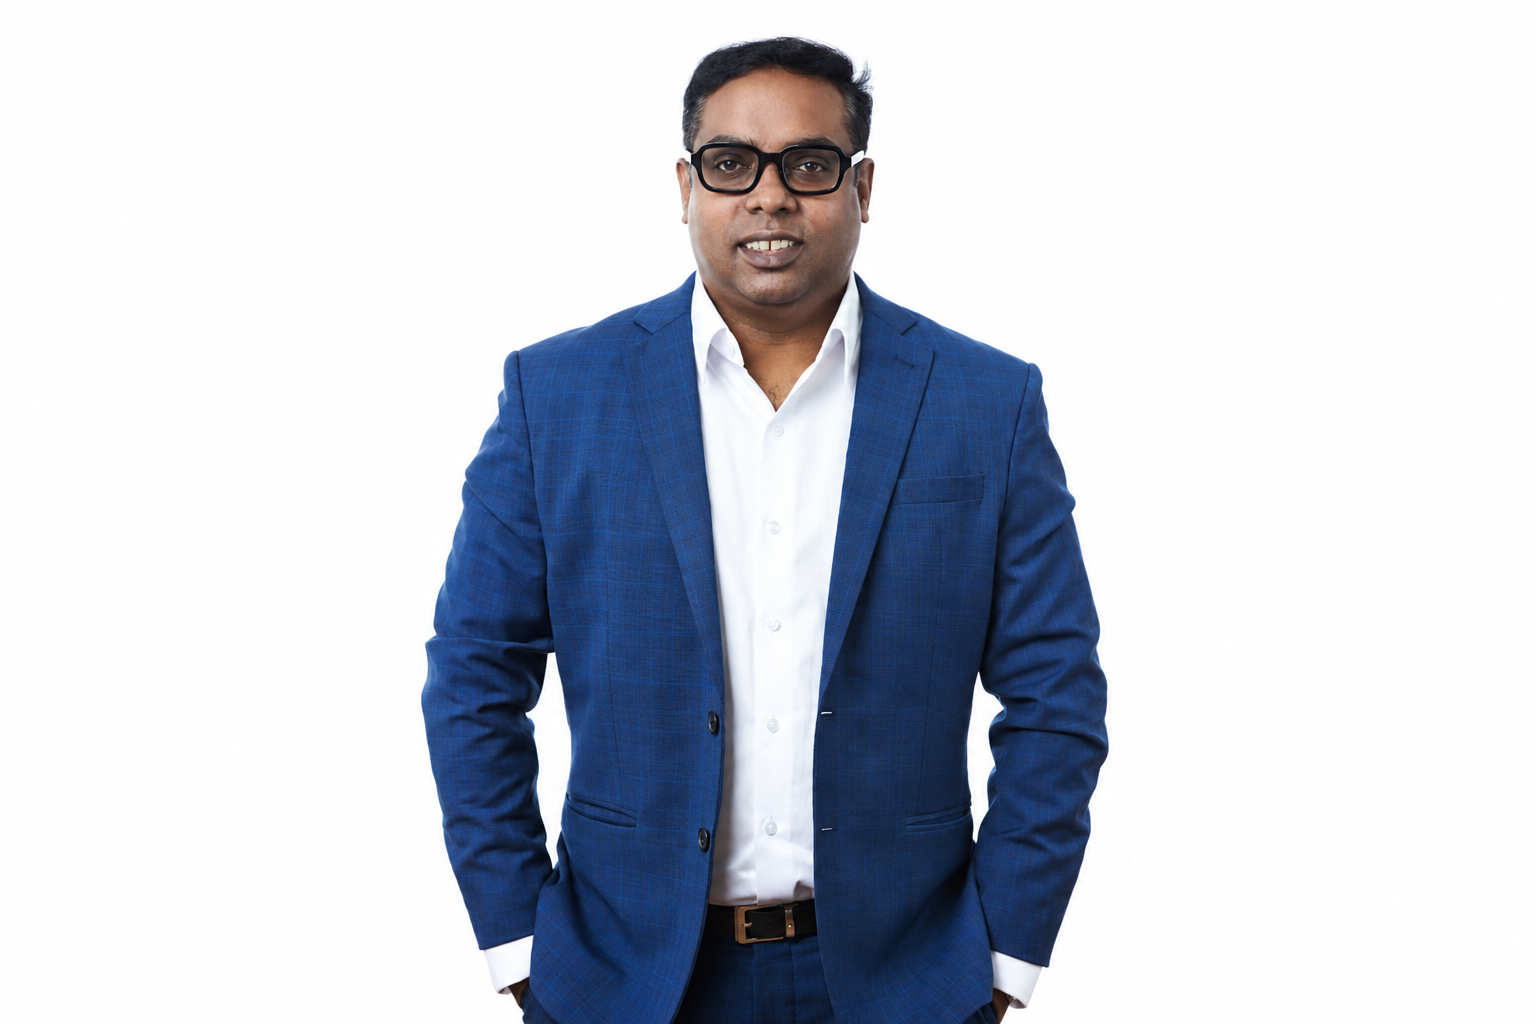
In this TNGlobal Q&A, Francis Thangasamy, Managing Director, APAC at Lumen Technologies, discusses enterprise AI readiness, federated learning, workload placement, governance, resilience and the metrics boards can use to judge whether AI investments are creating value.
Singapore’s new guidance on GenAI transparency and privacy-enhancing technologies sets expectations for responsible AI deployment. From an enterprise leadership perspective, what changes when these principles move from policy documents into day-to-day operations?
The real change is that responsible AI stops being the responsibility of one team. It becomes a day-to-day business discipline involving leaders across technology, security, data, legal and operations.
In my conversations across APAC, organizations are no longer asking whether they should adopt AI. They are asking how to use it safely and consistently across different markets, regulatory environments and technology estates.
That becomes more challenging once an AI system enters production. Public disclosures such as Chatbot Info Cards need to keep pace with changes in how the system behaves and uses data. With federated learning, organizations need to govern data and computing across multiple locations and parties.
For leaders, the priority is clear accountability. Someone must own the outcome, teams need visibility into how the system is operating, and there must be a process for acting when it behaves differently from what was intended or communicated.
Policy sets the expectation. The operating environment determines whether an organization can meet it consistently. That includes the network carrying the data, the security controls protecting it, and the visibility needed to understand what is happening across distributed environments.
What does enterprise AI readiness actually require beyond access to models and computing capacity? Where are organizations most commonly underprepared today?
A lot of attention has gone into models and computing capacity, but the model is only one part of the equation. The more difficult question is whether the business can depend on it every day.
A pilot can work well with a limited dataset and a small group of users. Production is where the real test begins. The AI system needs reliable access to trusted data, appropriate security controls, and infrastructure capable of supporting consistent performance as usage grows.
The priorities will not be the same for every business. A bank may begin with explainability, resilience and data controls. A manufacturer operating across several sites may focus first on latency, local processing and operational continuity.
If I had to identify the biggest area of underpreparedness, it would be the operating environment around the model. Many enterprises are trying to support AI workloads using infrastructure and governance designed for a different generation of applications.
Security is part of that challenge. Our Lumen Defender Threatscape report found that cyber threats are increasingly targeting network edge devices such as routers and firewalls. As AI becomes more distributed, organizations need to consider the security of the entire environment supporting it, including the infrastructure connecting users, data and workloads.
AI readiness therefore means knowing where the data comes from, who can access it and if the underlying network can deliver the required performance securely. Without that foundation, a successful experiment can become difficult to scale.
The GenAI chatbot transparency guidelines include measures such as chatbot information cards and clearer disclosures. What technical and operational capabilities are needed to ensure that these disclosures accurately reflect how an AI system behaves in production?
Chatbot Info Cards can help users understand an AI system, but they are useful only if they continue to reflect what it is actually doing.
Organizations need visibility into the data the system accesses, how it performs and whether its outputs remain within the boundaries communicated to users. Safeguards should identify unusual behavior, potential data exposure or material performance changes.
There must also be a process for updating disclosures when data sources, models or use cases change. Teams need to know who validates the information, approves updates, and acts when operational evidence does not match the published disclosure.
From our experience maintaining ISO 42001 certification, the key lesson is that AI governance is not a one-time exercise. It requires continuous oversight as the technology, data, and ways people use it evolve.
Privacy-enhancing technologies such as federated learning allow organizations to work with distributed data without centralizing the raw information. What infrastructure, network, and data-governance challenges must enterprises address before these approaches can operate reliably at scale?
Federated learning allows organizations to work with distributed data without bringing all the raw information into one place, but keeping the data local does not remove the operational challenge.
This is particularly relevant in Southeast Asia, where organizations operate across markets with different levels of digital maturity, infrastructure readiness and regulatory requirements.
Participating environments need resilient connectivity for frequent model synchronization. Each location must also have sufficient processing, storage and security capabilities.
Keeping data decentralized changes where risk must be managed. A Zero Trust approach, including strong identity controls and Zero Trust Network Access where appropriate, can help ensure that access by users, devices and workloads is continuously assessed and authorized.
Finally, participants must agree on access, validation, incident handling and decision rights. The technology may be distributed, but accountability cannot be.
How should enterprises decide whether an AI workload belongs in the public cloud, a private environment, on-premises infrastructure, or at the edge? What trade-offs should leaders consider around latency, security, data residency, cost, and performance?
There is no single right location for every AI workload. Leaders should start with the business requirement: what data is involved, how quickly the system must respond, where the data can be processed, and what happens if the service becomes unavailable.
Compute-intensive or variable workloads are often suited to the public cloud. A latency-sensitive use case, such as identifying a production-line defect, may require processing closer to the site. Sensitive or regulated workloads may be better placed in private or on-premises environments.
Cost must be assessed over the workload’s lifecycle, particularly if a pilot becomes a heavily used service.
Most large enterprises will use a combination of environments. The network connects those choices. If data cannot move securely and predictably between them, the flexibility promised by hybrid architecture can quickly become operational complexity.
Many organizations are under pressure to demonstrate returns from AI investments while also strengthening governance and compliance. How can leaders balance speed of deployment with the controls needed to manage risk?
There is understandable pressure to demonstrate returns quickly, but activity is not the same as value. Ten pilots do not necessarily create more value than one capability that solves a meaningful business problem.
I would begin with repeated sources of friction. Is AI reducing customer-resolution time, helping employees make decisions faster, removing manual work, or improving service reliability? Those are outcomes leaders can measure.
Governance should be built into the same process. When ownership, approved data sources, and risk boundaries are clear from the start, teams can move faster with greater confidence.
Leaders should also be prepared to stop initiatives that generate usage but not results. A disciplined program is not about launching the most use cases. It is about scaling the capabilities that create measurable value and can be operated responsibly.
Which investments should Singapore enterprises prioritize first when building compliant and resilient AI data pipelines? Is there a sensible sequence that organizations can follow rather than trying to modernize everything at once?
Singapore enterprises do not need to modernize everything at once, but they should address the foundations in the right order.
I would begin with data and connectivity. Leaders need to understand where important data resides, how it moves, and whether the network can support increased demand.
The next priority is security and identity, with consistent access controls, segmentation and visibility as more systems and users connect to AI services.
organizations can then determine where local computing or storage would reduce latency or support data-residency requirements. A manufacturer may need processing near a facility, while a financial institution may need to keep particular workloads within an approved jurisdiction.
Finally, each use case should be assessed against business value, data readiness, risk, and infrastructure requirements before substantial investment is committed.
What metrics should boards and senior leaders use to assess whether their AI infrastructure and governance investments are working? How should they measure readiness, resilience, compliance, and business value?
Boards should not assess AI primarily by the number of tools deployed or employees using them. The real question is whether AI is improving the business without creating unacceptable risk.
Readiness measures can cover data quality, capacity, availability and latency. Resilience measures should show how quickly issues are detected, how quickly services recover, and whether AI-enabled processes create new operational dependencies.
Compliance measures should establish that the organization knows where data resides, who can access it, and how exceptions are being addressed.
Business value must be tied to the original objective. That may include shorter customer-handling times, less manual processing, faster decisions, improved service levels, savings or revenue contribution.
The baseline should be agreed before investment is approved. Otherwise, boards may see growing AI activity without knowing if it has improved an outcome that matters.
Singapore is establishing a relatively advanced AI governance environment, but many enterprises operate across several Asia-Pacific markets. How can organizations build systems that meet Singapore’s expectations while remaining adaptable to different regulatory and data-residency requirements across the region?
For regional businesses, the challenge is creating consistency without assuming every APAC market is the same.
Organizations need a common regional foundation for identity, security, accountability, data provenance and auditability. Specific controls can then be adapted for local requirements covering consent, access, data handling and residency.
Some data and workloads may need to remain within a particular jurisdiction, while others can be processed regionally. The architecture must support those distinctions and provide visibility into where data moves and which controls apply.
Building an entirely separate operating model for every market adds complexity and can make governance less consistent. Singapore can provide a strong reference point, but regional leaders must translate that standard into an operating model that remains practical across different regulations, infrastructure conditions, and levels of digital maturity.
Looking ahead, how do you expect enterprise AI infrastructure and governance priorities to change over the next 12 to 24 months?
Over the next two years, the AI conversation will become less focused on models and more focused on outcomes. Boards will ask what the investment is delivering, what the business now depends on, and if it can be operated securely at scale.
Security will enter the discussion earlier. As AI draws on data and computing across cloud, data-centre and edge environments, organizations will need clear visibility into what is connected, how information is moving and where unusual behavior is emerging.
Data governance will also become more specific. It will not be enough to have an AI policy. Leaders will need to know where the data came from, whether it can be used for the intended purpose and who is accountable.
Access to powerful models will become increasingly common. The real difference will be if an organization can turn that access into something trusted, resilient and useful to the business.
Francis Thangasamy is Managing Director for APAC at Lumen Technologies, where he leads the region’s commercial strategy and operations. He has nearly 30 years of experience across technology and digital infrastructure.
Editor’s note: This Q&A has been lightly edited for clarity and TNGlobal house style. The substance of the interviewee’s responses has been preserved.
Share your perspective: TNGlobal welcomes contributed insights and expert commentary from across Asia’s technology and innovation ecosystem. Submit a contribution for editorial consideration, or explore more conversations in our TNGlobal INSIDER and TNGlobal Q&A and Interviews archive.
Sumsub’s Penny Chai on workforce identity risks in the AI era [Q&A]