Artificial intelligence infrastructure is spreading across multiple data-center sites as operators contend with power availability, land constraints and growing demand for high-capacity connectivity. The shift places more pressure on optical networks that connect compute clusters, cloud environments and the data feeding AI applications.
One example is CtrlS Datacenters’ planned optical network deployment in India, which will use Ciena technology to connect nine data centers across five metro networks. The companies said the deployment is designed to support up to 100 terabits per second of capacity. Beyond raw bandwidth, operators must weigh route diversity, network power requirements, time to activation and the cost of carrying increasingly distributed workloads.
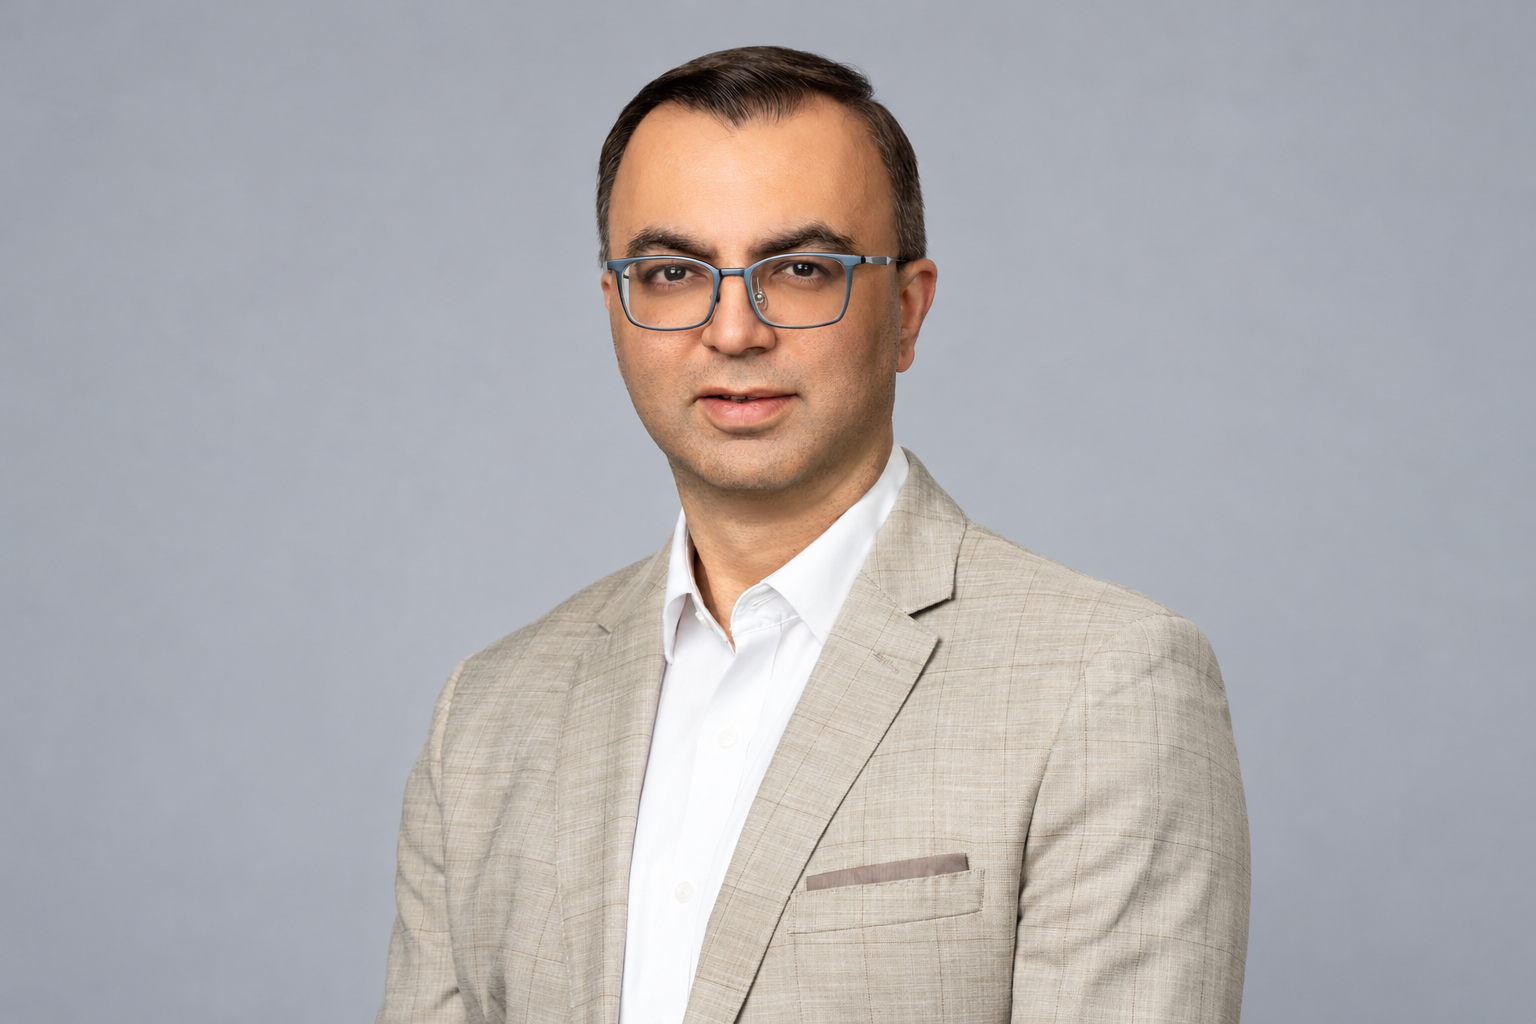
In this TNGlobal Q&A with Gautam Billa, Chief Technology Officer and Vice President of Sales Engineering for Asia Pacific, India and Japan at Ciena, we examine how AI workloads are changing inter-data-center traffic, when higher optical capacity becomes justified and what network designers can learn from emerging projects in India and Southeast Asia.
What traffic patterns created by AI training, inference and hyperscale cloud architectures are changing the assumptions operators used to make about inter-data-center connectivity?
Traditionally, networks were optimized for predictable, north-south traffic patterns, moving data between users and centralized applications. However, AI introduces highly distributed, data-intensive workloads that generate massive east-west traffic across data centers. Training clusters are no longer confined to a single location; they are distributed across multiple facilities due to power and space constraints. This creates a need for the network to act as the critical fabric connecting these distributed compute environments.
Traditional network traffic was also downlink heavy. A much higher percentage of traffic flowed from content locations to user locations (consumer, residential or enterprise). With AI, there is a growing percentage of upstream traffic as well. Inputs to AI factories need a lot of actual data, along with background and context to flow from the end user to the AI compute. This is changing the way networks were architected and modeled for traffic flow.
At what point does 100 Tb/s-class capacity become necessary rather than simply desirable? Which utilization, traffic-growth or service requirements would justify an operator moving to that scale?
The math of network scale in AI networks is not driven by user traffic only. AI companies are spending billions of dollars on AI training and fine-tuning infrastructure. Compute (GPUs) is one of the most expensive components in the setup and driving a high GPU efficiency (low idle time) is extremely critical to optimize investments. A high-scale network infrastructure is critical to drive and maintain high efficiency GPU clusters. Network investments in 100 Tb/s-class capacity networks are a small piece of the pie, and hence a necessity to drive highly efficient GPU clusters. The point at which that capacity becomes necessary is therefore not defined by utilization alone, but also by how quickly operators can plan, deploy, and turn up additional capacity before the network constrains the compute environment.
AI demand can be bursty and difficult to forecast. How should operators plan optical capacity when conventional multi-year traffic forecasts may be overtaken by a small number of large AI workloads?
There are a lot of leading indicators that provide reasonably accurate guidance on AI network capacity. Power and real estate are the key indicators. Note that it takes at least 18 to 24 months for any AI facility to get the physical infrastructure (land and buildings) and power in place.
Depending on the size of the data center (20 MW, 100 MW, or 1 GW), it is possible to estimate baseline connectivity requirements. Of course, the applications running inside the data center define the exact network capacity with higher accuracy, but it is possible to do the groundwork to connect the facility in advance such as the laying ducts and creating fiber route diversity. In some cases, operators could also lay the photonic gear in advance. They can further reduce activation time by completing design validation, site-readiness assessments, and deployment planning before demand becomes firm. For traffic, operators could create a central pool of inventory for urgent requirements and replenish the pool as they take gear out to fulfill demand.
Software is equally important. Ciena’s Navigator Network Control Suite (Navigator NCS) combines real-time performance data, AI-powered analytics, planning and multi-layer control so operators can see emerging constraints and activate capacity faster.
For distributed AI infrastructure, how do operators balance latency, resilience and cost when deciding which workloads or datasets can be split across metro or longer-distance data-center sites?
The right split starts with the workload. Tightly coupled training may demand high throughput, deterministic performance and low jitter between sites, while data preparation, checkpointing, replication and some inference functions can tolerate greater distance.
I would recommend classifying workloads by data volume, synchronization needs, sovereignty, recovery objectives and the cost and availability of power and compute,not by latency alone. That distinction matters because scale will be the dominant issue for many AI environments even where latency is manageable.
High-capacity optical Data Center Interconnect (DCI), integrated routing and genuine path diversity allow distributed facilities to function as one logical infrastructure pool. Operators can then place compute where economics and policy make sense while engineering the network to deliver the required service level.
How are coherent optics, network automation and real-time telemetry changing the amount of usable capacity operators can extract from existing fiber before adding new routes?
Fiber is finite and increasingly valuable, so the first priority is to extract more from each pair. For example, Ciena recently worked with Telstra to transport four 400GbE client services over a single wavelength, without regeneration, operating in L-band spectrum between Melbourne and Sydney on a live production network. This milestone is significant because it means that operators can unlock significantly more capacity by extending beyond the traditional C-band into L-band spectrum.
The hardware layer is only part of the answer. Navigator NCS ingests, correlates, and analyzes real-time telemetry to provide visibility into performance and available margin, helping operators extract the maximum capacity from their hardware assets. This includes advanced spectrum defragmentation to rearrange wavelength assignments to release continuous spectrum that can be allocated to new channels, or fine-tuning amplifier settings to mine the latent system margin to deliver more network capacity. Combined with network engineering and operational expertise, this helps operators move from identifying a constraint to implementing the required capacity change more quickly and with greater confidence.
Does the rise of multi-site GPU clusters change east-west traffic patterns enough to require a different optical network topology or protection strategy?
Large, synchronized east-west flows make oversubscribed hub-and-spoke designs and single-corridor dependencies more significant. Ciena describes this as scale-across: connecting dispersed GPU clusters with the capacity, predictability and operational simplicity normally associated with a single environment. This involves simple, ultra-high density, point-to-point C- and L-band systems, power-efficient coherent pluggables and enough restoration capacity to protect priority workloads.
Power is increasingly a constraint for AI infrastructure. Which network-efficiency metrics, such as watts per transported bit, should operators track, and how meaningful are optical-network savings relative to compute and cooling demand?
Operators should track watts per transported bit, but also capacity per rack unit, energy per delivered service, regeneration sites, equipment utilization and stranded capacity. These measures connect optical efficiency to the power and space constraints shaping AI infrastructure.
There is higher-capacity coherent technology available today, such as Ciena’s WaveLogic 6 Extreme that can carry more traffic on existing fiber, reduce the number of transponders and regeneration points, at lower cost and power per bit.
Optical networking does consume less energy than GPUs and cooling, but the savings are still material at scale: every watt and rack unit removed from the network can be redirected to compute. The relevant question is therefore not the network’s share of total facility power, but whether the complete architecture delivers more useful AI capacity from each constrained resource.
As more AI traffic is concentrated across high-capacity corridors, which failure modes become more consequential and how should operators design for route diversity and recovery?
Critical services need physically diverse routes, enough spare capacity to restore services without creating a second congestion event, optical-layer encryption where sensitive data is in motion, and regularly tested recovery procedures. This requires ongoing operational discipline, including validating restoration capacity, maintaining accurate network data, and periodically exercising recovery plans rather than assuming that designed protection will perform as expected. Real-time assurance can then actively monitor network health to confirm that restoration paths retain the capacity and performance the workload requires, or require recalculation.
What constraints in India’s data-center market are particularly important for network design today, and which of those lessons are likely to apply to Southeast Asia and the wider Asia Pacific region?
India shows how AI is shifting network planning from hubs to corridors. Power and large land parcels are pushing new facilities toward the outskirts of Tier 1 cities and into additional locations, while fiber quality, route diversity, subsea access and time to market remain critical.
The lesson for Southeast Asia is similar: compute is expanding beyond established hubs as markets such as Johor and Indonesia offer land and power, while sovereignty and subsea geography shape placement. Operators should plan DCI, metro, terrestrial and subsea connectivity as one fabric. Ciena’s role is to help them scale that fabric through high-capacity coherent optics, routing, automation and managed optical service models.
What indicators would tell an operator that it is overbuilding inter-data-center capacity, or conversely that it is already falling behind AI-driven demand?
Overbuild appears when utilization stays structurally low, committed demand repeatedly slips, and capacity cannot be redeployed or monetized through high-value wave services – this is not necessarily the case today.
Falling behind looks different: turn-up times lengthen, large requests require bespoke engineering, restoration headroom is consumed in normal operation, or customers cannot obtain 400G and 800G services where they need them.
Ciena’s Wave Services report points to strong growth in high-capacity connectivity. An adaptive optical foundation, with coherent capacity added in modules and software providing a single point of control, lets operators preserve strategic headroom without locking into a one-time forecast. Equally important is the ability to plan, stage, and activate that capacity predictably, so available technology can be converted into customer-ready services when demand materializes.
Gautam Billa is Chief Technology Officer and Vice President of Sales Engineering for Asia Pacific, India and Japan at Ciena. Based in Singapore, he has more than two decades of experience in telecommunications and networking and has worked with cloud and telecom service providers across Asia, Europe and the Middle East. He joined Ciena in 2011.
Editor’s note: This Q&A has been lightly edited for clarity and TNGlobal house style. The substance of the interviewee’s responses has been preserved.
Share your perspective: TNGlobal welcomes contributed insights and expert commentary from across Asia’s technology and innovation ecosystem. Submit a contribution for editorial consideration, or explore more conversations in our TNGlobal INSIDER and TNGlobal Q&A and Interviews archive.