As businesses experiment with AI agents, one of the practical decisions is where those models and workflows should run. Cloud services provide access to large frontier models and elastic computing, while local inference can give companies more control over sensitive documents, meetings and internal knowledge.
Singapore-based Estha is taking the latter approach with a private AI workforce for Apple Silicon. TNGlobal reported on the launch earlier this month, which combines meeting intelligence, document processing, presentation creation and spreadsheet analysis with tools for building private chat applications.
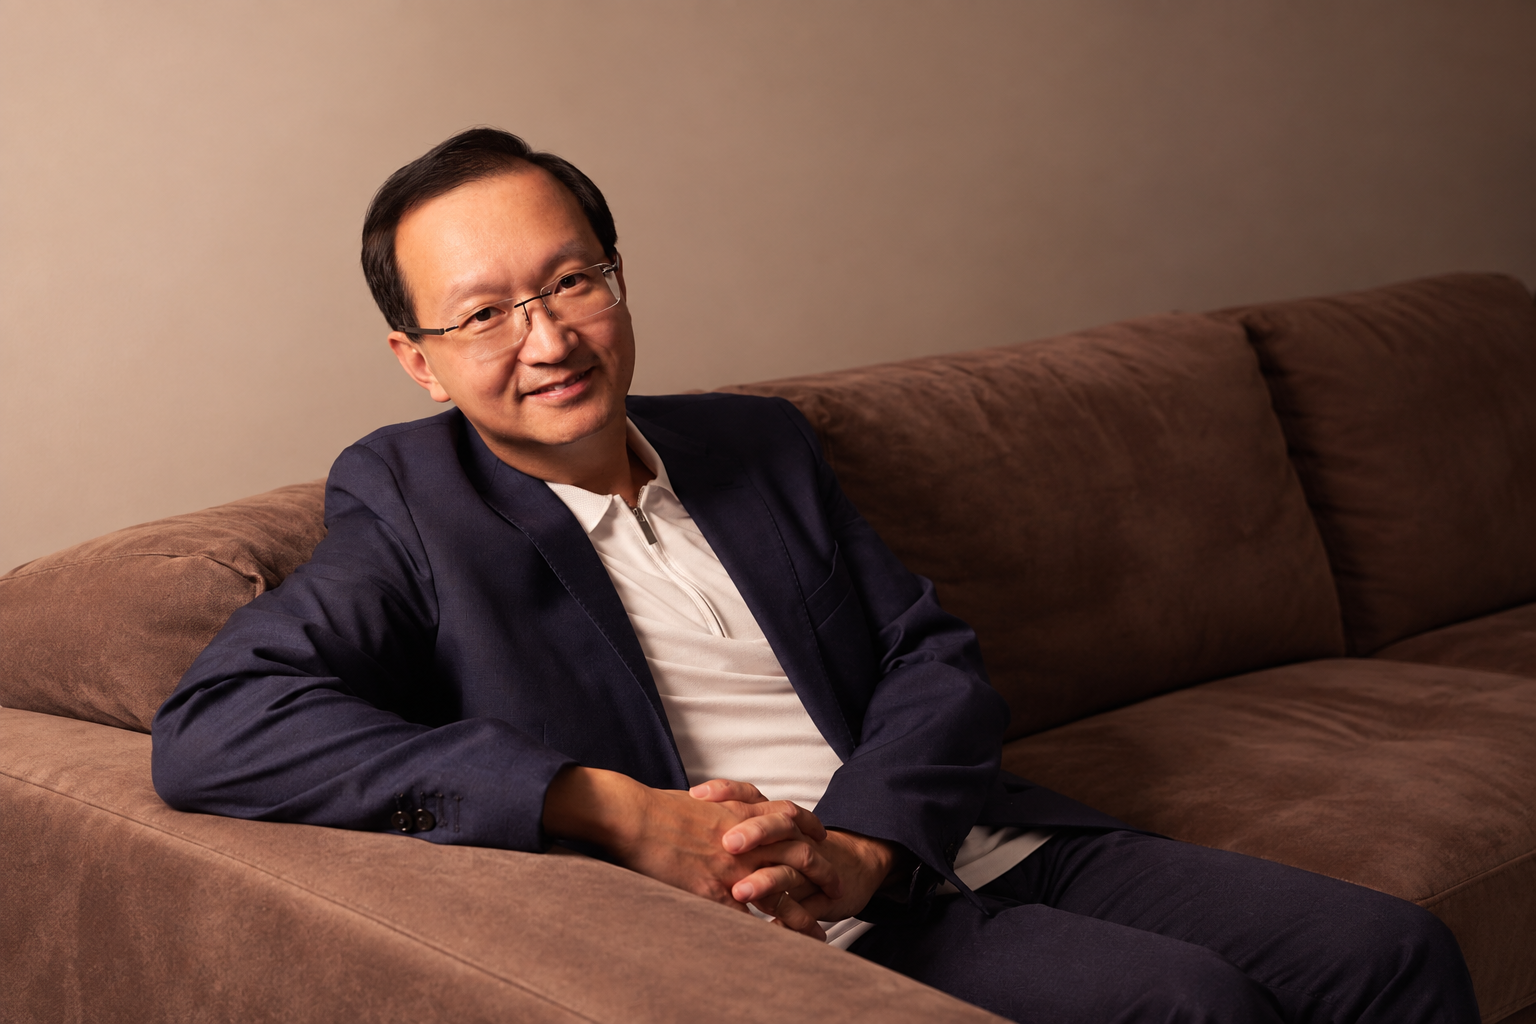
In this TNGlobal Q&A, Eric Lam, Co-Founder and Creator of Estha, discusses which workloads are already practical on-device, the trade-offs with cloud inference, endpoint security, governance, cost, SaaS integration and what would signal broader SME adoption.
Estha is positioning on-device AI as a privacy and cost advantage for SMEs. Which workloads are genuinely practical to run locally today, and where do users still need cloud models or external services?
The strongest case for local AI today is where the information being processed is confidential, proprietary or strategically important enough that the organization would prefer it to remain within an environment it controls. That can include customer information, financial records, legal documents, contracts, internal strategy, meeting records and proprietary company knowledge.
The workloads already practical locally are usually bounded, repeatable tasks such as document analysis, internal knowledge retrieval, meeting intelligence, and extracting or comparing information across company documents. But privacy alone is not enough. One reason SMEs have struggled with private AI is that traditional on-premises deployments can involve considerable engineering and integration work. Estha is designed to make private AI usable straight out of the box, rather than requiring an SME to spend months assembling infrastructure before it gets value from AI.
We do not believe everything must run locally. Cloud services remain useful for live external information, certain highly compute-intensive workloads and services that inherently sit outside the organization. The better question is therefore: which parts of my company’s work and intelligence should remain under my control, and which genuinely need to go outside?
What are the main trade-offs between local and cloud inference in terms of model quality, speed, context length and hardware requirements?
Local and cloud inference optimize for different things.
On model quality, cloud services provide access to the largest frontier models, while local models are constrained by what fits and runs well on the device. For bounded SME workflows such as document analysis, meeting intelligence and internal knowledge work, however, local models can already be capable enough. The relevant test is whether the system completes the business task reliably, not whether it uses the largest available model.
On speed, local inference removes network round-trips and vendor queues, although performance still depends on the chip, memory bandwidth and model size. Cloud inference can be faster on large GPUs, but latency varies with connectivity and service load.
On context length, cloud services make very large windows easier to access. Locally, the model and its working context share the machine’s memory, so long documents are often handled through retrieval, chunking and hierarchical summarization.
On hardware, local AI requires capable Apple Silicon with sufficient unified memory. Around 16GB is better suited to lighter chat and document tasks, while we prefer 32GB or more for heavier agent workloads. Cloud shifts that hardware requirement into subscriptions or metered usage, while inference takes place outside the customer-controlled environment.
Estha remains model-agnostic: we select models according to the workflow and available hardware, so the customer does not have to become an infrastructure expert first.
Estha says supported workflows can run without an internet connection after installation and model download. How are model updates, security patches and new capabilities handled without weakening the privacy argument?
Offline operation does not mean a device can never connect to the internet. There is an important distinction between downloading something into the customer’s environment and uploading the customer’s information out of it. A customer can connect when required to receive Estha software updates, security patches, additional capabilities or supported models, while the business information being processed by supported local workflows remains within the customer’s controlled environment.
The point is this: updating Estha should not require us to see or process the customer’s underlying business information. Being model-agnostic is also important here. We continually evaluate suitable models and can add them to our repertoire as technology evolves. Customers are therefore not buying Estha because of one particular LLM. They are buying the private AI environment, the agents and the workflows, with the underlying models selected to support those jobs.
Keeping data on-device removes one class of risk, but it also puts more responsibility on the endpoint. How should SMEs think about device theft, malware, local user permissions and backups when sensitive AI workloads are running on a Mac?
Local does not mean risk-free. It removes one class of exposure, routinely sending information to an external AI inference service, but it places greater importance on the security of the company’s own environment. SMEs still need appropriate endpoint controls: disk encryption, strong authentication, managed user permissions, endpoint protection, backups and, where appropriate, remote-device management.
The principle should also be that AI does not bypass existing access controls. If an employee is not entitled to see a confidential finance folder, an AI agent should not become another route for that employee to access it. Ultimately, private AI should sit inside the company’s security and governance framework, not outside it.
For document analysis, meetings and internal knowledge, what controls does Estha provide around retention, deletion, access and visibility into what information an agent has used?
Our starting principle is that the customer retains control of both the information and the AI environment.
Today, the strongest control is architectural: for supported local workflows, source material, outputs and company knowledge remain on the customer’s device or within another customer-controlled environment, rather than being sent to an external inference service by default. Retention and deletion can therefore be managed within the customer’s own storage and device-management policies rather than being determined by an external AI provider.
AI should also respect the company’s existing access model. An agent should not become a back door into files or knowledge that a user is not authorized to access. For enterprise deployments, we are developing more granular governance over who can use particular agents, which knowledge they can access and what actions those agents are permitted to take.
Traceability is equally important. Take our Data Analyst agent: when it produces a figure or recommendation that informs a real decision, the operator should be able to see which local datasets or files were used and how the analysis was derived, then decide where human review is required. The same principle applies to meeting and document-analysis workflows. For consequential work, an answer alone is not enough; accountability must remain with the organization, and explainability is an important function of that.
Zero metered token cost is attractive, but local AI still has hardware, support and management costs. At what usage level or company profile does the economics of on-device AI start to make sense compared with enterprise cloud AI?
There is no universal break-even point. For occasional AI use, cloud services can make very good economic sense. But the equation changes when AI becomes part of daily operational work, like repeated document processing, meetings, internal knowledge, analysis and multiple employees using agents continuously. At that point companies start comparing recurring consumption costs against hardware they can own and amortize.
There is another cost that is often overlooked: deployment complexity. Traditional private AI can require infrastructure specialists, integration projects and ongoing engineering support. Our approach is different. Estha is intended to behave much more like a finished business product: install it, select the appropriate capability or agent and start using it, rather than beginning with a lengthy AI infrastructure project. And where confidentiality is important, the economics are not simply dollars per token. The ability to use AI on information the company otherwise would not be comfortable exposing externally has value of its own.
How do you evaluate whether a local model is good enough for a business workflow? What accuracy, hallucination or task-completion benchmarks should SMEs look at before trusting an agent with confidential work?
I would discourage SMEs from choosing AI simply because a particular model has the highest score on a general benchmark. The right benchmark is the organization’s actual work. Take representative documents and tasks, define what correct output should look like and test repeatedly. Did the system identify the required information? Were the facts right? What was omitted? Did it introduce unsupported information? Did the workflow reach the expected outcome?
This is also why the agent and workflow layer is important. A business is not employing a model; it is trying to complete a job. For an agent, task completion and reliability can matter more than eloquence. And where the consequence of an error is significant, there should be an appropriate human review point. AI should make people substantially more productive; it should not automatically remove accountability from the process.
Many SMEs already rely on SaaS systems for CRM, accounting and collaboration. How far can a private local agent integrate with those systems without sending sensitive data back into the cloud or creating broad new permissions?
This is where the word “private” needs to be used carefully. If an agent accesses a cloud CRM or accounting platform, that external platform obviously remains in the cloud. Connecting a local agent to it does not make the SaaS system local.
The appropriate architecture should therefore give the agent only the information and actions necessary for its job rather than broad credentials. Where practical, confidential knowledge and reasoning can remain local, while only the minimum required information is exchanged with an external service. I expect many enterprise architectures will ultimately be hybrid. But the private AI layer remains valuable because the organization can decide what stays inside, what is allowed outside and under what conditions, instead of assuming every piece of information has to flow through an external AI system.
Estha is initially optimized for Apple Silicon. How much does that hardware dependency shape the addressable market, and do you expect the model to expand to Windows or other enterprise environments?
It does narrow the immediate market for running the full Estha stack directly on an endpoint, because many enterprises remain predominantly Windows-based. We chose Apple Silicon because it provides a highly integrated and relatively consistent platform for running substantial AI workloads locally.
But our enterprise direction does not require every employee to own a Mac. We are developing Windows client access from a Mac-based machine that operates as the company’s private AI server, so a predominantly Windows organization can still benefit from Estha without replacing its existing endpoint estate. The AI workload and sensitive company knowledge can remain within the company-controlled local environment, while users work from the devices they already use.
Our philosophy is simple: the underlying infrastructure should increasingly disappear from the user’s perspective. Businesses should be able to deploy a private AI workforce without having to redesign their entire IT environment around it.
Over the next 12 months, what would convince you that private/on-device AI has moved from a niche privacy use case into a mainstream SME deployment model in Singapore and the wider region?
I would look at repeat operational use. The strongest signal would be companies starting with one private AI use case, seeing it work and then expanding into several workflows. Employees would begin using agents every day in finance, operations, compliance, management and other business functions rather than treating AI as an occasional experiment.
Another signal would be SMEs deploying private AI without needing specialist AI teams or lengthy implementation projects. That is when the technology has genuinely crossed into the mainstream.
Today, private AI can know the company’s information and perform defined business tasks. Our roadmap ultimately moves toward governed autonomous agents that can learn approved workflows, decisions, corrections and exceptions. At that point, the organization is no longer merely consuming AI. It is gradually building its own company-owned organizational intelligence. That is the long-term opportunity we see: private AI that is easy to deploy today, but which can ultimately become a compounding asset specific to how that company works.
Eric Lam is Co-Founder & Creator of Estha, a Singapore-based company developing private AI tools and agents designed to run on customer-controlled hardware.
Editor’s note: This Q&A has been lightly edited for clarity and TNGlobal house style. The substance of the interviewee’s responses has been preserved.
Share your perspective: TNGlobal welcomes contributed insights and expert commentary from across Asia’s technology and innovation ecosystem. Submit a contribution for editorial consideration, or explore more conversations in our TNGlobal INSIDER and TNGlobal Q&A and Interviews archives.